 EN
 RO
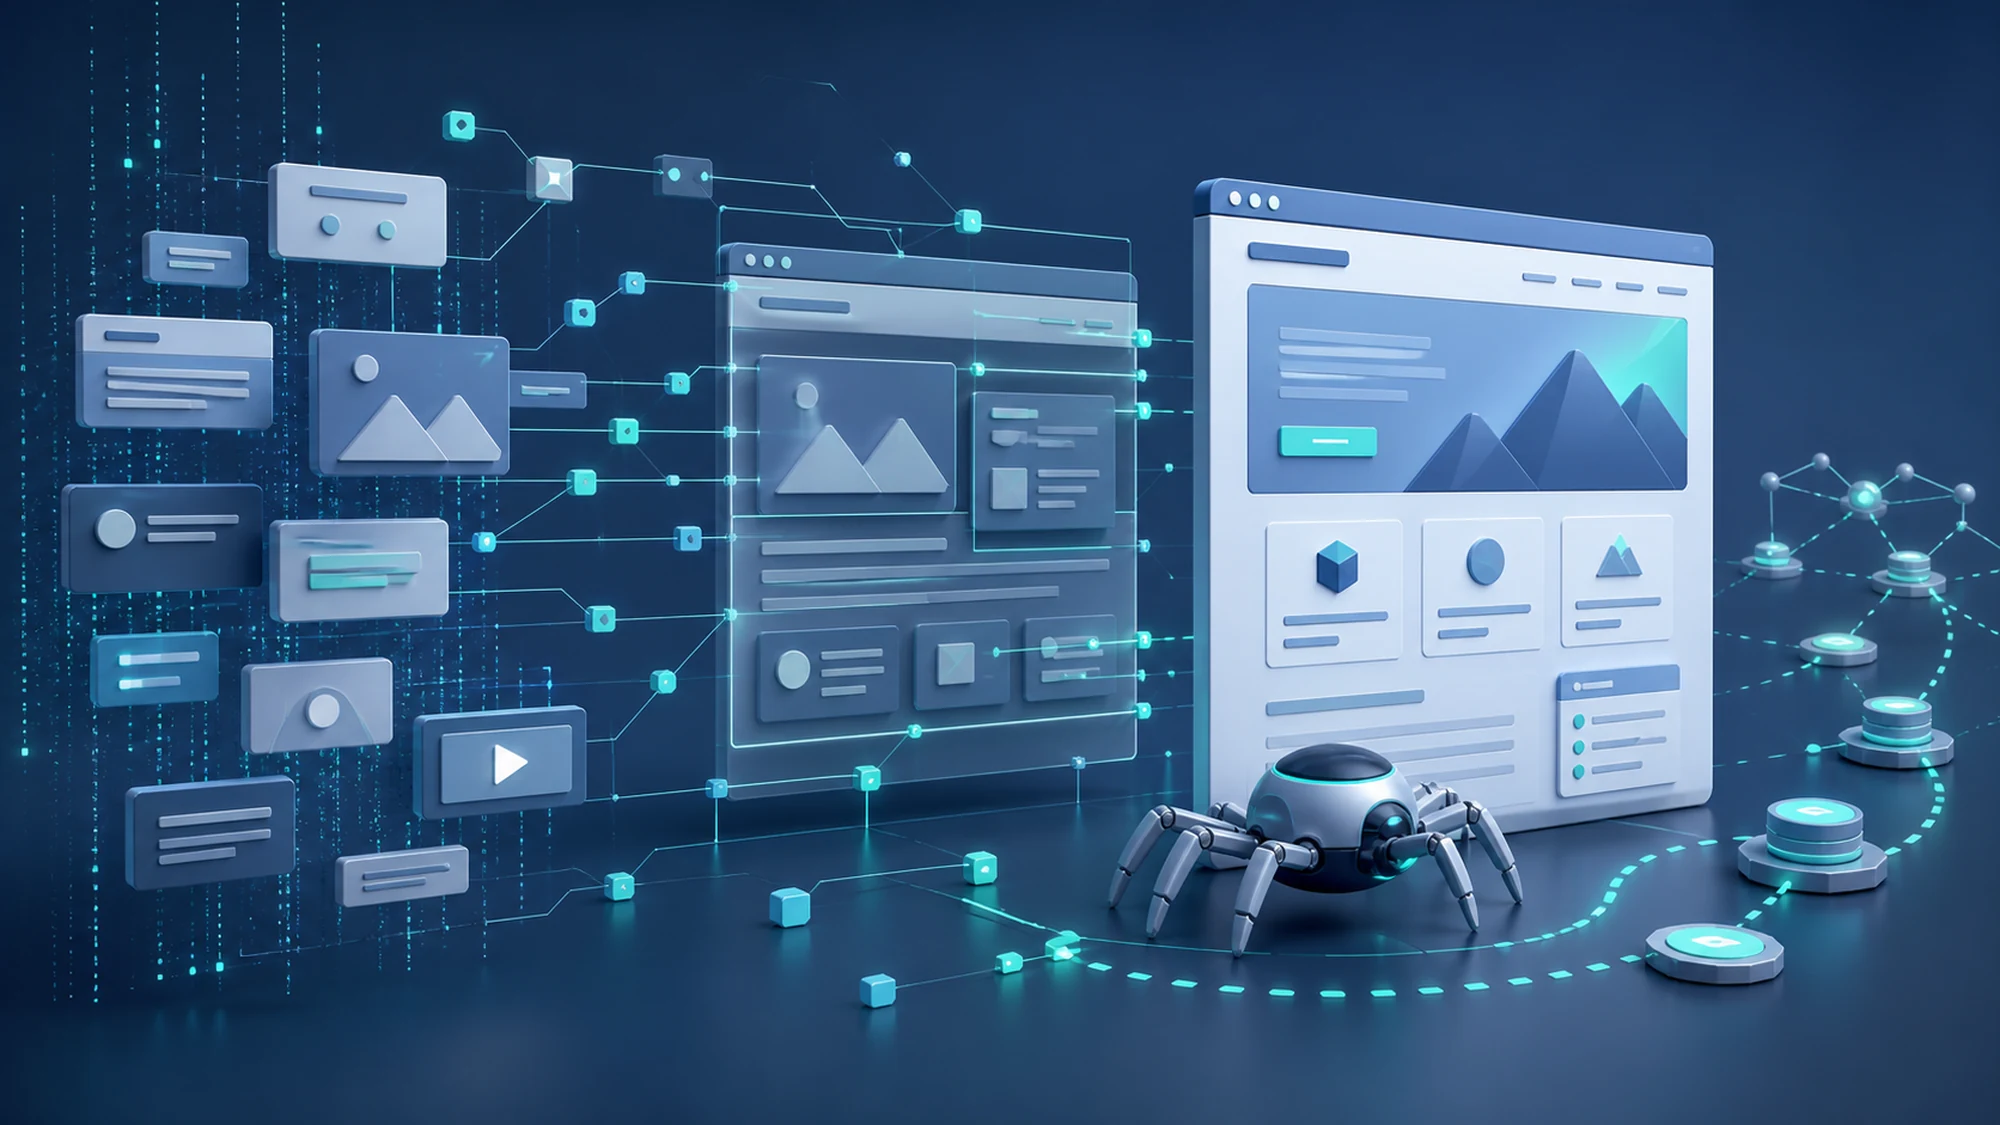
A site built in React or Vue can look perfect in the browser and still be nearly invisible to Google if the main content only exists after JavaScript executes in the user's browser. Googlebot can render JavaScript, but it does so in a separate stage, with limited resources and delays, and other crawlers (Bing, social media bots, some AI indexing tools) either don't render JavaScript at all or do so only partially.
The practical solution isn't to abandon React or Vue, but to choose the right rendering strategy (server-side, static, or hybrid), expose essential content before hydration, and constantly verify, with concrete tools, what Google actually sees on your page.
This guide explains, step by step, what client-side rendering means from a crawler's perspective, which technical problems appear most often, and how to prevent or fix them, with examples that apply to real projects.
What client-side rendering means for a crawler
In a classic site, server-side rendered (SSR) or static, the server sends the browser an HTML file that already contains the title, text, and links of the page. In a Single Page Application (SPA) built purely client-side, the server sends an almost empty HTML, usually a single <div id="root"></div>, and the actual content is generated later by JavaScript, directly in the browser.
For a human user, the difference is invisible, because the browser executes the script immediately. For a crawler, however, JavaScript execution is a separate and costly stage: Google first downloads the raw HTML, queues it for rendering, then, when resources are available, executes the scripts and sees the final content. This second stage can take anywhere from a few minutes to several days, depending on the crawl budget allocated to the site.
Other crawlers or agents (some social media preview tools, older crawlers, some AI content indexing tools) may not execute JavaScript at all, in which case they see exactly the initial HTML, empty or incomplete.
How Google actually indexes a JavaScript site (two-wave rendering)
Google explicitly describes the process in its official Search Central documentation: crawling and indexing a JavaScript site happen in two distinct waves.
- First wave (initial crawling): Googlebot downloads the raw HTML and extracts the links and static content available immediately. If the application depends entirely on JavaScript, Google sees very little at this step.
- Render queue: the URL is placed in a waiting queue until Google allocates the resources needed to execute the JavaScript, using an updated Chromium version (Web Rendering Service).
- Second wave (rendering and final indexing): after the script executes, Google re-evaluates the content, extracts the title, text, and links that appear after hydration, and integrates them into the index.
The delay between the two waves is the main reason new pages in a purely client-side SPA appear in the index more slowly, and internal links generated only after rendering can be discovered and followed with significant delay compared to an SSR site.
The most common crawling and indexing issues in React and Vue
Most technical SEO problems in JavaScript applications fall into a few recurring patterns, regardless of whether the framework used is React, Vue, Angular, or something similar.
| Issue | Technical cause | Effect in Search Console |
|---|---|---|
| Content missing from the index | Main text only exists after hydration, and Google's rendering fails or times out | "Discovered - currently not indexed" or "Indexed, though blocked by robots.txt" |
| Internal links not discovered | Navigation uses JavaScript handlers (onClick) instead of real <a href> tags | Deep pages not indexed, sitemap as the only discovery source |
| Identical meta tags on every page | Title and meta description are set only through JavaScript, after rendering, at different times per page | Incorrect or generic titles and descriptions in search results |
| Content blocked from rendering | JS/CSS files required for rendering are blocked via robots.txt | Explicit "Page with resource loading issues" warning in Search Console |
| Duplicate content across routes | Client-side routing (History API) without distinct canonical URLs per page state | URLs canonicalized incorrectly or consolidated incorrectly by Google |
When to choose SSR, SSG, or partial hydration for a new project
Choosing the rendering strategy is the technical decision with the highest SEO impact in a React or Vue project. There's no universally correct solution, just a simple criterion: how often the content changes and how critical it is for it to be indexed quickly.
- Static Site Generation (SSG): suited for relatively stable content (service pages, blog articles, brand pages). The complete HTML is generated at build time, so Google receives the final content directly, without waiting for rendering. Frameworks like Next.js or Nuxt offer native SSG for React and Vue respectively.
- Server-Side Rendering (SSR): suited for dynamic content (product pages with variable stock and price, internal search results, partially personalized content). The server generates the complete HTML on every request, then JavaScript takes over in the browser (hydration).
- Partial hydration / islands architecture: suited for large sites with mixed zones of static content and complex interactions, where only the components that need interactivity are hydrated, the rest stays static HTML.
- Pure Client-Side Rendering (CSR): acceptable for applications that don't need visibility in search engines (internal dashboards, admin panels, post-login applications). Not suited for public pages that need to appear in search results.
For a new public site built in React or Vue, the default choice should be SSR or SSG, not pure CSR, precisely to avoid dependence on Google's render queue described above.
Migrating from pure CSR to SSR/SSG: practical steps without rewriting the app from scratch
For an existing project already built as a client-side SPA, a full migration to SSR can be costly. There is, however, a set of intermediate steps that significantly reduce the risk of incomplete indexing, without requiring a complete rewrite.
- Identify the public pages critical for SEO (service, product, article pages) and separate them from private/post-login areas, which don't need server-side rendering.
- Add SSR or SSG only for the identified pages, using a framework that supports hybrid rendering (Next.js for React, Nuxt for Vue), leaving the rest of the application unchanged.
- Replace navigation based purely on JavaScript with real links (
<a href="/page">), so the crawler discovers routes without waiting for script execution. - Move title and meta description settings out of late-rendered components into the initial rendering step (server-side or at build time), not just inside
useEffector the Vue equivalent. - Generate an automatically updated XML sitemap on every new content publication, as an additional discovery source alongside internal links.
- Test every critical page with the URL Inspection tool in Search Console, comparing the HTML rendered by Google with what a user sees in the browser.
Common risks and how to prevent them
Even after choosing SSR or SSG, technical traps can remain that partially cancel out the benefit of server-side rendering. The most common ones, in real projects, are the following.
- Incomplete hydration content ("empty flash"): the initial HTML contains the correct content, but the component re-renders empty for a fraction of a second during hydration, and in some setups this empty state is what Google's rendering captures. Mitigation: verify through URL Inspection that the final rendered HTML contains the text, not just the server's initial HTML.
- Blocking JS/CSS resources in robots.txt: an old practice, inherited from the era when JS files were blocked for crawl budget reasons. Today, blocking these resources prevents Google from rendering the page correctly. Mitigation: explicitly allow access to the JS and CSS files required for rendering.
- Canonical set only client-side: if the canonical tag is injected by JavaScript after rendering, there's a risk Google will temporarily use the raw, pre-render URL for canonicalization decisions. Mitigation: set the canonical tag in the HTML delivered by the server, not just through JavaScript.
- Slow rendering response (TTFB and Time to Interactive): SSR implemented incorrectly (without proper caching) can slow down the server, affecting Core Web Vitals and, implicitly, the crawling experience. Mitigation: use page/route-level caching (edge caching, ISR in Next.js) for public pages that don't change on every request.
- Infinite routes generated dynamically (facets, parameters): filters and URL parameters generated client-side can create nearly infinite URL variations, consuming crawl budget. Mitigation: canonicalize to the parameter-free version and control facet indexing through robots meta tags, not just robots.txt.
How to actually verify what Google sees on your page
It's not enough to assume rendering works correctly; verification must be done explicitly, for every critical page type, using concrete tools, not just visual inspection in the browser.
| Tool | What it checks | When to use it |
|---|---|---|
| URL Inspection (Search Console) | HTML rendered by Googlebot, blocked resources, indexing status | After every new page launch or major routing change |
| "Pages" report (Search Console) | Site-wide causes of non-indexing ("Discovered - currently not indexed", "Duplicate, Google chose different canonical") | Monthly, as routine monitoring |
| View Source vs. Inspect Element | Difference between the raw HTML sent by the server and the final DOM after JavaScript execution | Quick troubleshooting for a page that doesn't appear in the index |
| curl or an HTTP client without JavaScript | What a crawler that doesn't execute JavaScript at all receives | Quick test, no visual tools needed, for critical content (title, H1, links) |
A practical decision rule: if the main text, H1 title, and critical internal links of a public page don't appear in the server's raw response (without JavaScript execution), that page depends entirely on Google's render queue and should be treated as an indexing risk, no matter how good it looks visually in the browser.
Practical implementation plan (checklist)
- Identify the public pages that need to be indexable and separate them from private areas.
- Choose the rendering strategy per page type: SSG for stable content, SSR for dynamic content.
- Replace JavaScript-based navigation with real
<a href>links. - Set title, meta description, and canonical in the initial HTML, not just client-side.
- Allow access in robots.txt to the JS/CSS files required for rendering.
- Generate and submit an automatically updated XML sitemap on every publication.
- Verify every critical page through URL Inspection after launch.
- Monitor the "Pages" report in Search Console monthly for non-indexing signals.
Frequently asked questions about technical SEO on JavaScript sites
Do React or Vue automatically hurt SEO?
Not automatically, it depends on the rendering strategy chosen. A React or Vue site rendered server-side (SSR) or statically (SSG) can have SEO performance identical to a classic HTML site. Problems appear when the application is built as a pure client-side SPA, without any form of server rendering.
Does Google index JavaScript or not?
Yes, Google can execute JavaScript through its Web Rendering Service, but this happens in a second stage, separate from initial crawling, and consumes additional resources from Google. Rendering isn't instant and isn't guaranteed to happen at the same pace for every page.
Is an XML sitemap enough for an SPA without SSR?
The sitemap helps with URL discovery, but it doesn't solve the problem of content that only exists after JavaScript executes. Without SSR or SSG, a page can be discovered through the sitemap and still remain unindexed if rendering fails or is delayed.
What's the difference between SSR and static prerendering?
SSR generates HTML on every request, on the server, suited for content that changes often. Static prerendering (SSG) generates HTML once, at build time, suited for relatively stable content. Both solve the same underlying problem: they deliver complete content to the crawler, without depending on client-side rendering.
How do I know if my current site has a real indexing problem caused by JavaScript?
Compare the server's raw response (without JavaScript execution, for example via curl) with what you see in the browser. If the title, H1, and main content are missing from the raw response, and the "Pages" report in Search Console shows pages in "Discovered - currently not indexed" status, the problem is most likely related to client-side rendering.
Conclusion
Technical SEO for JavaScript sites doesn't mean giving up on React or Vue, it means consciously choosing the right rendering strategy for each page type and constantly verifying, with concrete tools, what Google actually sees, not just what a user sees in the browser. A public site built purely client-side remains an indexing risk, no matter how good it looks visually, and SSR or SSG remain the safest directions for pages that need to appear in search results.
Want to check whether your React or Vue application has real crawling and indexing issues? Let's discuss a technical audit.
Write a comment