 EN
 RO
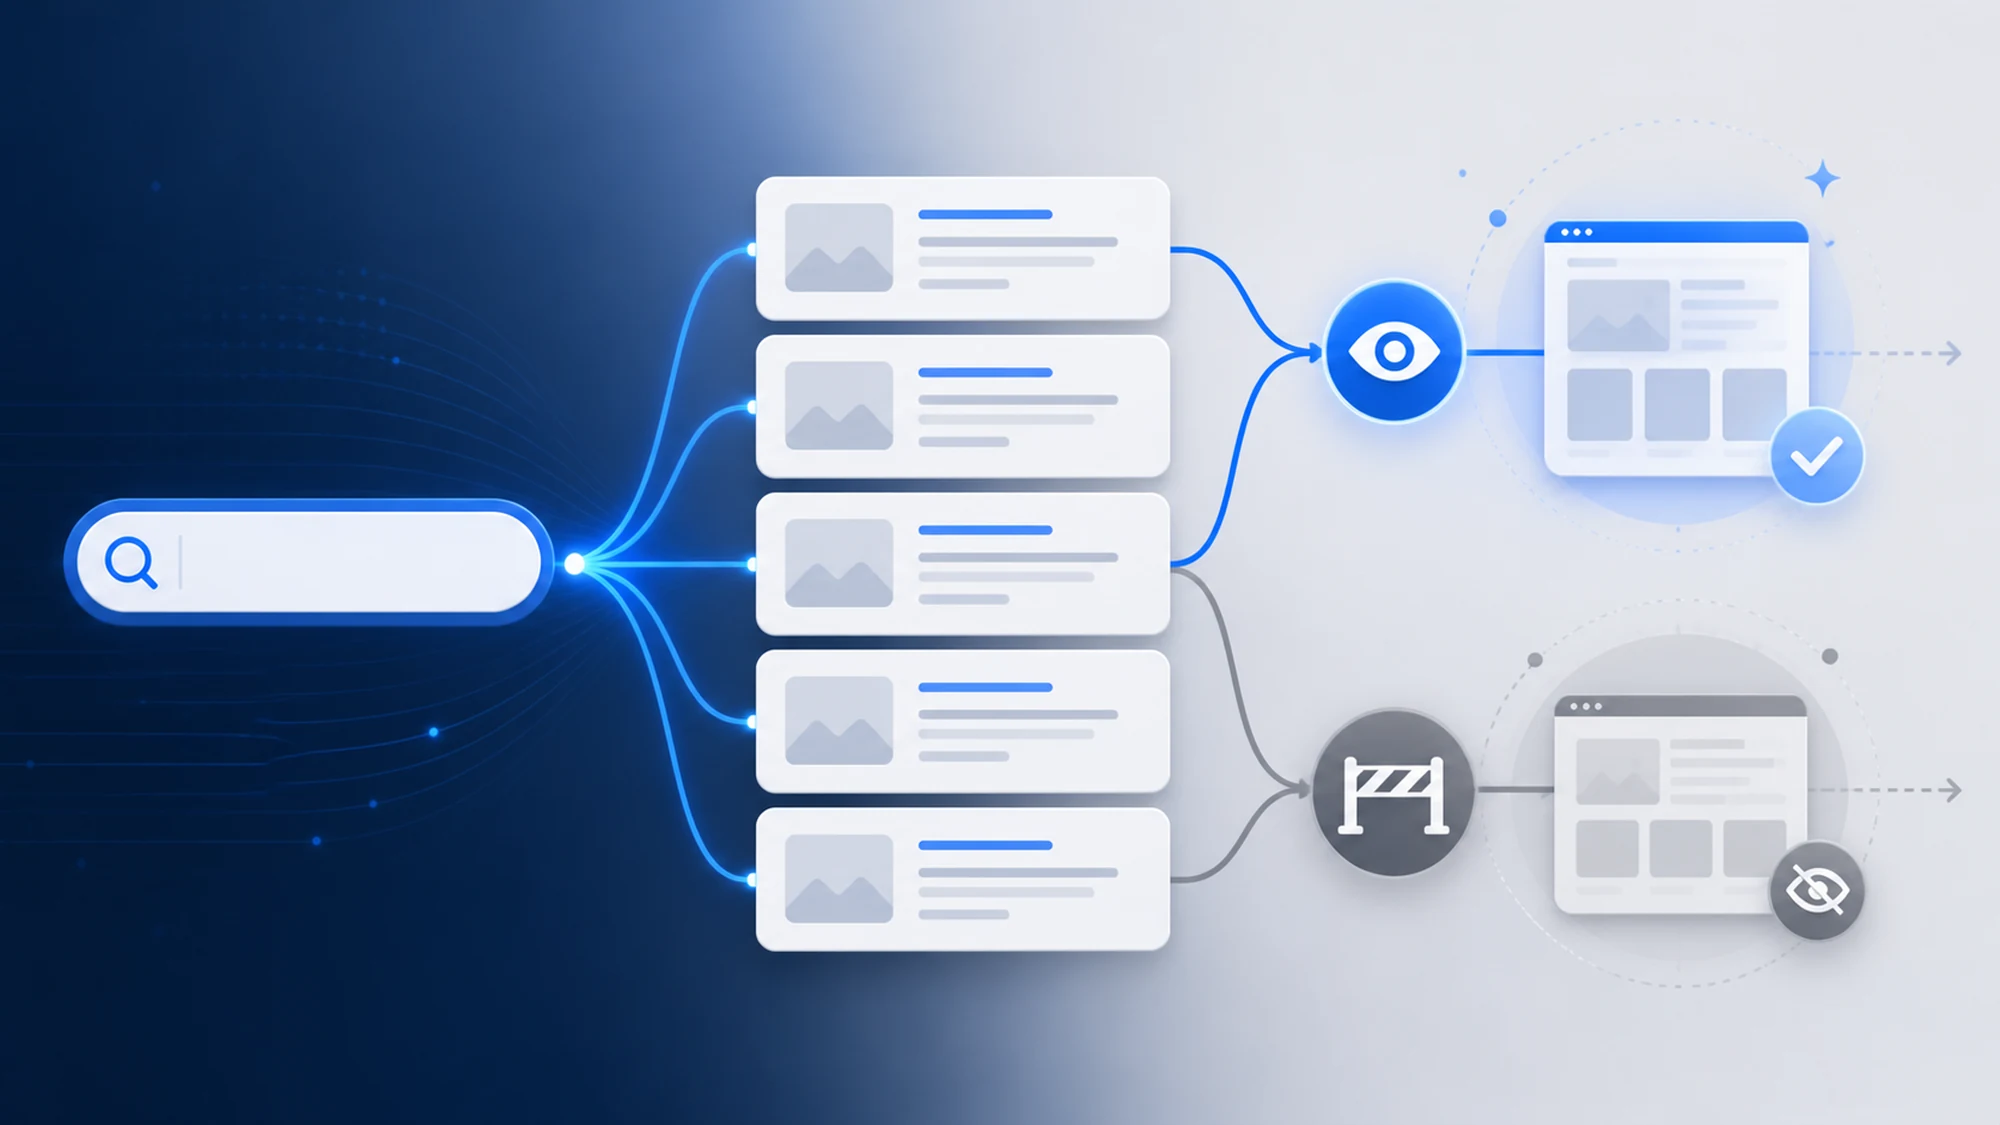
Pages generated by a website's internal search engine (site search) should, in most cases, not be indexed by Google. They appear automatically for every term a visitor types, produce thousands of near-identical URLs, and consume crawl budget without adding value to organic results.
The problem rarely comes from total neglect. It usually comes from a technical decision made without thinking about SEO impact: a search plugin installed with default settings, a URL with a ?s= or ?q= parameter left crawlable, or a results page that never gets an explicit noindex tag.
This guide explains why internal search pages so often become thin content in Google's eyes, when there's a real exception worth indexing, and what combination of noindex, canonical, and robots.txt keeps them from draining crawl budget and diluting perceived site quality.
Why internal search pages are usually thin content for Google
An internal search results page typically shows a generic title ("Results for: [term]"), a list of links to other pages on the site, and little or no original text. From Google's perspective, this structure looks like thin content: the page doesn't answer the search intent on its own, it just points visually toward other pages that do.
The risk grows with the number of terms searched. A site with average traffic can generate tens of thousands of unique search URL combinations in a year, one for every misspelling, synonym, or term variation a visitor types in. If those URLs are crawlable and indexable, Google treats them as real site pages, even though most have zero organic visitors and no unique content value.
The most common side effect is crawl budget dilution: Googlebot spends time accessing thousands of internal search pages instead of recrawling product, category, or article pages more often, the ones that actually need to stay fresh in the index.
How to check if your internal search pages are already indexed
Before deciding on an action, verify whether the problem already exists on your site. Three quick checks, in recommended order:
- Google's
site:search operator — searchsite:yourdomain.com inurl:searchor the equivalent parameter your site uses (inurl:?s=,inurl:?q=). Any results confirm indexing. - Google Search Console — Pages coverage report — filter indexed URLs by the internal search URL pattern and check the total number of affected pages.
- robots.txt and page source — check whether the search URL is blocked in
robots.txtand whether<meta name="robots" content="noindex">is already present in the<head>of those pages.
If you find internal search pages already indexed with steady organic traffic (a rare but possible situation for very specific product-related terms), don't remove them abruptly — the correct treatment for that particular case is covered in the exception section below.
When indexing an internal search page is justified (the exception, not the rule)
The general rule is noindex, but one scenario justifies indexing: when an internal search page actually answers a real Google search intent, not just a query typed by someone already on the site. The most common example is an online store with a "search by OEM code" or "search by brand+model" function, where the searched term matches a specific, recurring commercial need.
In that case, the page should be treated as a real category page, not a generic search results page: it needs a unique title, a descriptive H1, manually written intro content, and a clean URL, not a raw query parameter. In practice, it stops being a "search results" page and becomes a landing page built on top of the search structure.
For every other case, free-text search using generic terms typed by users, indexing brings no benefit and increases the risk of thin content at scale.
Noindex, canonical, or robots.txt: the difference and when to use each
These three mechanisms solve different problems and are not interchangeable. Picking the wrong one either leaves pages indexed by mistake or wastes crawl budget unnecessarily.
| Mechanism | What it does | When to use it |
|---|---|---|
noindex, follow | Removes the page from the index, but Google can still crawl the links on it | The main solution for internal search pages: they stay functional for users, they disappear from Google results |
| Canonical to the category page | Tells Google which page is the "official" version, but doesn't guarantee exclusion from crawling | Useful when a search query actually returns the same product set as an existing category — avoids conflict between the two URLs |
| Disallow in robots.txt | Blocks crawler access to the URL, but doesn't guarantee removal from the index if the page already has external links | A supplementary step, not a standalone fix — reduces crawl budget spent, but doesn't replace noindex for already-indexed pages |
The recommended combination for most sites is noindex, follow directly on the search page, plus URL parameter exclusion in Google Search Console (where the parameter handling setting is still available) or clear robots.txt rules for search parameter variants.
Common mistakes and how to avoid them
The most frequent issues with internal search pages happen at implementation, not at the strategy level:
- Applying noindex and Disallow at the same time, incorrectly. If you block the URL in robots.txt, Google can no longer access the page to read the
noindextag, so a page already indexed before the block can stay in the index indefinitely, with no visible content in the search snippet. Apply noindex first, let the page drop out of the index, and only then consider blocking it via robots.txt to save crawl budget. - Empty search results not handled correctly. When a search returns no results, the page should show a clear message and respond with a 200 status, not generate an empty page that can be perceived as a soft 404.
- Internal links pointing to search pages. Menus, breadcrumbs, or "popular searches" widgets that link directly to internal search URLs pass link equity to pages that shouldn't be in the index in the first place.
- Multiplied search parameters. Filters combined with the search term (sorting, price, brand) can generate dozens of URL variants for the same query, without a clear parameter rule, each variant becomes a separate crawlable URL.
- Sitemap.xml accidentally including search URLs. A misconfigured sitemap generator can automatically include any URL the crawler accesses, including internal searches, check periodically that the sitemap only contains real pages.
Practical implementation plan
The steps below cover both sites where the problem already exists and setting things up from scratch:
- Identify the exact URL pattern used by the internal search engine (parameter, subfolder, or dedicated slug).
- Add
<meta name="robots" content="noindex, follow">to the<head>of the template used by search pages, not just the ones already indexed. - Check Google Search Console for already-indexed search pages and request removal after applying noindex, using the URL Inspection tool.
- Remove any internal link (menu, widget, breadcrumb) pointing directly to an internal search URL.
- Configure
robots.txtto block redundant parameter variants (sorting, filters combined with search), after noindex has had time to take effect. - Check sitemap.xml and remove any internal search URL included by mistake.
- If an exception case exists (a search term with real commercial value, see the section above), turn that search into a dedicated category page with a clean URL and its own content.
- Monitor Search Console for 4-8 weeks to confirm the drop in search-type pages in the coverage report.
Internal search vs category pages: when to turn one into the other
The key difference is intent. A category page exists regardless of user action and has a fixed, predictable set of products or articles. A search page only exists as a response to a variable, unpredictable input typed by anyone, at any time.
When Search Console data (checked before applying noindex) shows that certain internal search queries generate steady, relevant organic traffic, the right move isn't to leave them indexed as search pages, it's to "promote" them to permanent category page status: clean URL, its own H1, written intro content, and normal internal links pointing to it. That way you keep full editorial and technical control over the page, instead of letting Google index a dynamically generated page with no stable content.
Frequently asked questions about internal search page SEO
Should internal search pages always be excluded from the index?
In most cases, yes, because they're dynamically generated, vary based on input, and lack unique content. The exception is when a specific query shows real organic traffic and clear commercial value; in that case, turn the search into its own category page instead of leaving it indexed as a search result.
Does noindex affect visitors using the site's search function?
No. The noindex tag only affects the page's presence in Google's results. The internal search feature stays fully functional for site visitors.
Is robots.txt enough on its own, without noindex?
No. Robots.txt blocks crawler access, but a page already indexed or linked externally can remain in the index even without being recrawled, since Google can no longer see the noindex tag once access is blocked. Apply noindex first, then, optionally, robots.txt.
Does a canonical to the category page solve the problem on its own?
Canonical is a signal, not a strict instruction, Google can choose to ignore it if the two pages aren't similar enough. For internal search pages, noindex is the safer, more direct solution.
How do I quickly check if I already have internal search pages indexed?
Search Google for site:yourdomain.com inurl: followed by the parameter or slug your search function uses (e.g. inurl:?s= or inurl:search). Any result confirms there are indexed pages that need to be handled.
Conclusion
Internal search pages shouldn't compete with a site's real pages for crawl budget and index visibility. The practical rule stays simple: noindex by default for all dynamically generated search results, no internal links pointing to them, and promotion to full category page status only for the terms that Search Console data proves deserve permanent page status.
Want to check if your site has internal search pages indexed by mistake? Let's discuss a technical audit.
Image generated with AI, used for illustrative purposes.
Write a comment