 EN
 RO
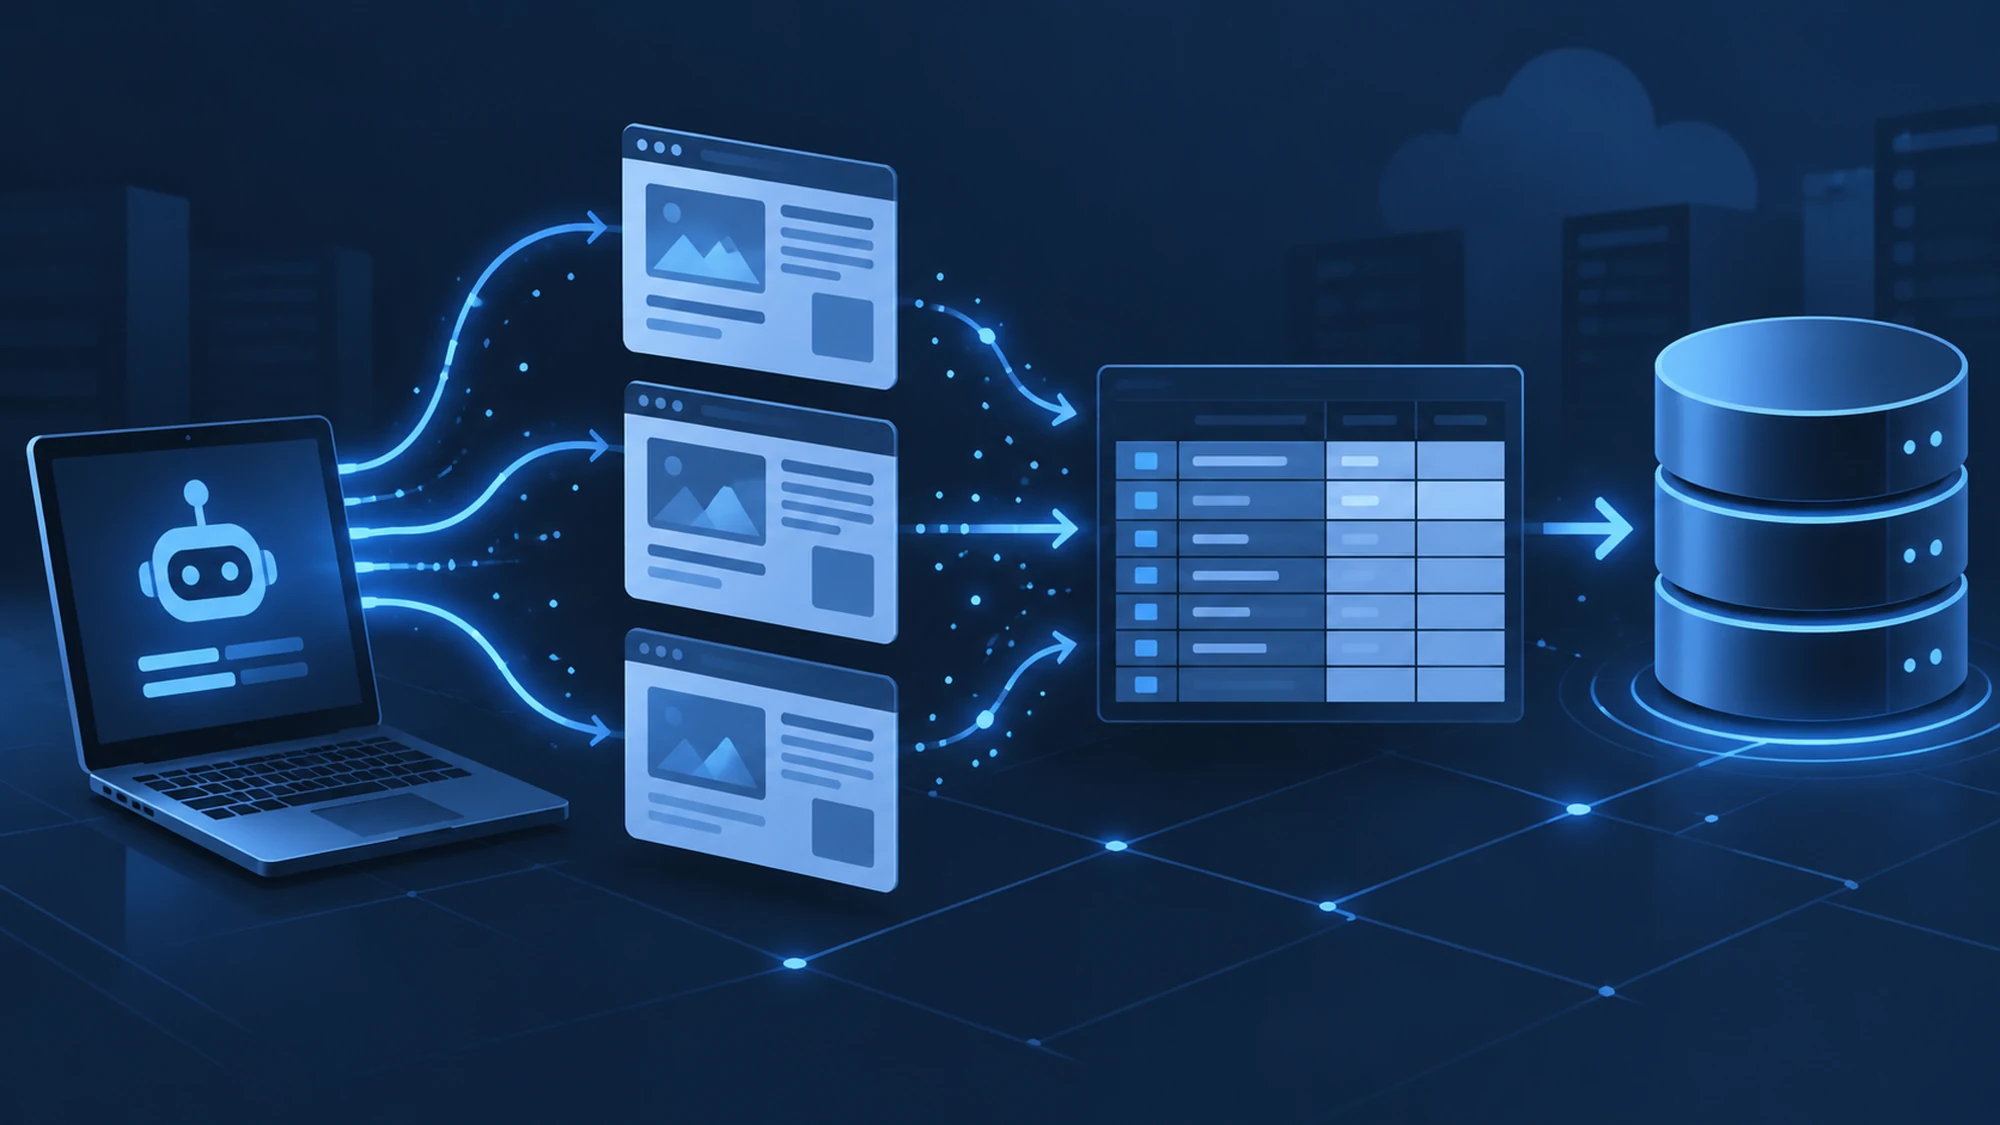
A crawling bot works through five repeating steps: it sends a request to a web page, downloads the response, extracts the relevant information from the page's code, structures it into a usable format (a table, a database, a file), and moves on to the next page. There's no magic involved and it isn't an "intelligent" process on its own — it's a script that repeats these steps thousands of times per hour, faster and more consistently than any manual work could.
The term can sound abstract if you've never worked with this directly, but the mechanism behind it is easy to follow once broken down into steps. This article walks through each stage of a crawling script, from the first request sent to a site to the moment the data becomes usable in a catalog, a price report, or an internal database.
This is useful if you want to understand what happens "under the hood" before commissioning a crawling or web scraping project, or if you're evaluating internally whether such a process is feasible for the data sources you need.
What a crawling bot actually is
A crawling bot is a program (script) that accesses web pages automatically, instead of a human user clicking through each link manually. The term crawling describes the systematic process of moving through pages (from one page to another, following links or a list of URLs), while scraping describes the actual extraction of data from the content of those pages. In practice, the two terms are almost always used together, since a script rarely performs only one of these operations.
A third important term is parsing — the process by which the script "reads" a page's HTML code and identifies exactly where the needed information sits (product title, price, code, description), based on the page's structure (HTML tags, CSS classes, attributes).
Step 1: the script sends a request to the target page
Everything starts with a list of URLs (page addresses) the script needs to visit. For each URL in the list, the script sends an HTTP request to the server — essentially the same request your browser sends when you type an address and hit Enter.
The target site's server receives the request and typically responds with the page's HTML code. This exchange — request sent, response received — is the basic step, repeated for every page on the list. A well-built script sends these requests at controlled intervals, not all at once, specifically to avoid overloading the target server.
Step 2: downloading and reading the server's response
Once the response arrives, the script first checks a few basic things: whether the page actually exists (status code 200) or whether it returned an error (deleted page, redirect, temporary block). If the response is valid, the script temporarily stores the page's HTML content so it can be analyzed in the next step.
At this stage, the script doesn't yet "understand" the content — it only has the raw text of the page, exactly as it appears in the source code. The actual interpretation of the information happens during parsing.
Step 3: parsing the HTML and extracting the data
This is the central part of the process. The script uses precise rules (called selectors) to locate, within the HTML code, exactly where each piece of relevant information sits: the product title might be in an <h1> tag with a specific CSS class, the price in a <span> with another class, the product code in a hidden attribute.
These selectors are written based on the specific structure of the target site — which is why a crawling script is usually custom-built for each data source, not a universal tool that works identically on any site. If the page structure changes (for example, the target site redesigns itself), the selectors need to be adjusted, otherwise the script stops extracting data correctly.
Step 4: cleaning and structuring the extracted data
Data extracted "raw" from HTML is rarely ready to use directly. A price might appear as text like "1,299.00 lei" instead of a numeric value, a product code might have extra spaces or characters, a description might contain leftover HTML tags. In this step, the script normalizes these values: converting text into numeric format where needed, removing unnecessary spaces and characters, and standardizing the data format (for example, the same currency and date format across all records).
Simple validations can also happen here: if an extracted price is 0 or a required field is missing, the record can be flagged for manual review instead of being automatically saved as correct.
Step 5: saving the data in a usable format
After cleaning, the data is saved in the format set for the project: an Excel/CSV file, a relational database, or an XML/JSON feed, depending on how it will be used (direct import into an online store, a price-monitoring report, integration with another system). The delivery format is usually decided at the start of the project, based on the system the data will end up in.
Step 6: repeating the process and following new links
A crawler rarely stops after a single page. In most cases, the script also identifies new links on the current page (for example, products from a paginated category) and adds them to the list of pages to visit. The process repeats until all relevant pages have been covered.
For ongoing projects (not just a one-time extraction), the script runs on a schedule, at a set frequency — daily, every few hours, or weekly — depending on how often the data changes at the source and how critical its freshness is for the business.
What can stop or slow down a crawling bot
Not every site can be accessed automatically without restrictions, and a serious crawling project accounts for this from the planning stage.
- The robots.txt file — most sites publish a
robots.txtfile indicating which parts of the site automated bots may access and which are excluded. A responsible crawler checks and respects these directives. - Rate limiting — if the script sends too many requests in a short time, the target server may temporarily block access. The correct solution is introducing controlled pauses between requests, not bypassing the block.
- Structural changes — a redesign of the target site can "break" existing selectors, and the script needs to be updated to keep extracting data correctly.
- Dynamically generated content (JavaScript) — some pages load data later, via JavaScript, not directly in the initial HTML; a crawling script needs to be built differently for these cases.
The general recommendation, regardless of the source, is to always check the target site's terms of use and robots.txt file before starting an extraction project, and for unclear legal situations, to consult a specialist. These aspects are covered in detail in our guide on legal crawling, robots.txt and GDPR.
Custom script, ready-made tool, or external service
Once you understand the steps above, a natural question follows: who builds and maintains this script?
| Option | When it makes sense | What it involves |
|---|---|---|
| Ready-made tool (no-code) | Simple extraction, a single source, small volume | Quick setup, but limited flexibility on complex sites |
| Custom script, in-house team | You already have available developers and recurring projects | Full control, but requires development time and ongoing maintenance |
| Dedicated external service | Multiple sources, complex structures, periodic updates without in-house effort | Script customized to the target source, delivery in the required format, maintenance included |
The main difference compared to a generic tool is that a custom script, built for a specific source, adapts exactly to that page's structure and can be updated quickly if the target site changes its design — something a one-size-fits-all solution can't guarantee.
Practical checklist before starting a crawling project
- Have you clearly defined which data you need extracted (exact fields: title, price, code, stock, image)?
- Have you checked robots.txt and the target site's terms of use?
- Have you set the collection frequency (one-time, daily, weekly)?
- Have you set the delivery format (Excel, database, XML/CSV feed)?
- Do you have a plan for when the target site changes its structure?
Frequently asked questions about how a crawling bot works
Is a crawling bot the same as a Google bot?
The basic mechanism is similar (HTTP request, reading HTML, following links), but the purpose differs. Google's bot indexes pages for the search engine, while a business crawling bot extracts specific data (prices, products, stock) for a defined purpose, usually internal.
Does a crawling script need special access to the target site?
No, it normally accesses the same public pages an ordinary visitor would see, without authentication. If the needed data is only available behind a login, the situation is handled differently and requires explicit verification of permissions.
How long does it take to extract data from a site?
It depends on the number of pages and the pauses enforced between requests (to avoid overloading the target server). A catalog with a few thousand products can take anywhere from a few minutes to a few hours, depending on these settings.
What happens if the target site changes its design?
The selectors the script uses to find the data no longer match the new structure, and extraction either stops or returns incomplete data. The script needs to be adjusted for the new structure — which is why ongoing crawling projects usually include periodic maintenance.
Can a crawling script extract any information from any site?
No. Availability depends on the target site's permissions (robots.txt, terms of use) and on how the page is built (static content vs. JavaScript-generated). A serious project checks these limitations before estimating what can actually be extracted.
Conclusion
A crawling bot is nothing more than a script that repeats, at scale, a simple sequence: request a page, read the response, extract data according to precise rules, clean it up, and save it in a usable format. The real complexity lies in the details — each site's structure, legal and technical limits, long-term maintenance — not in the basic concept.
If you want to automate data collection for your store or for market research, contact us for a personalized offer, tailored exactly to the sources you need. You can also see the full details of our web crawling data collection service.
Image generated with AI, used for illustrative purposes.
Write a comment