 EN
 RO
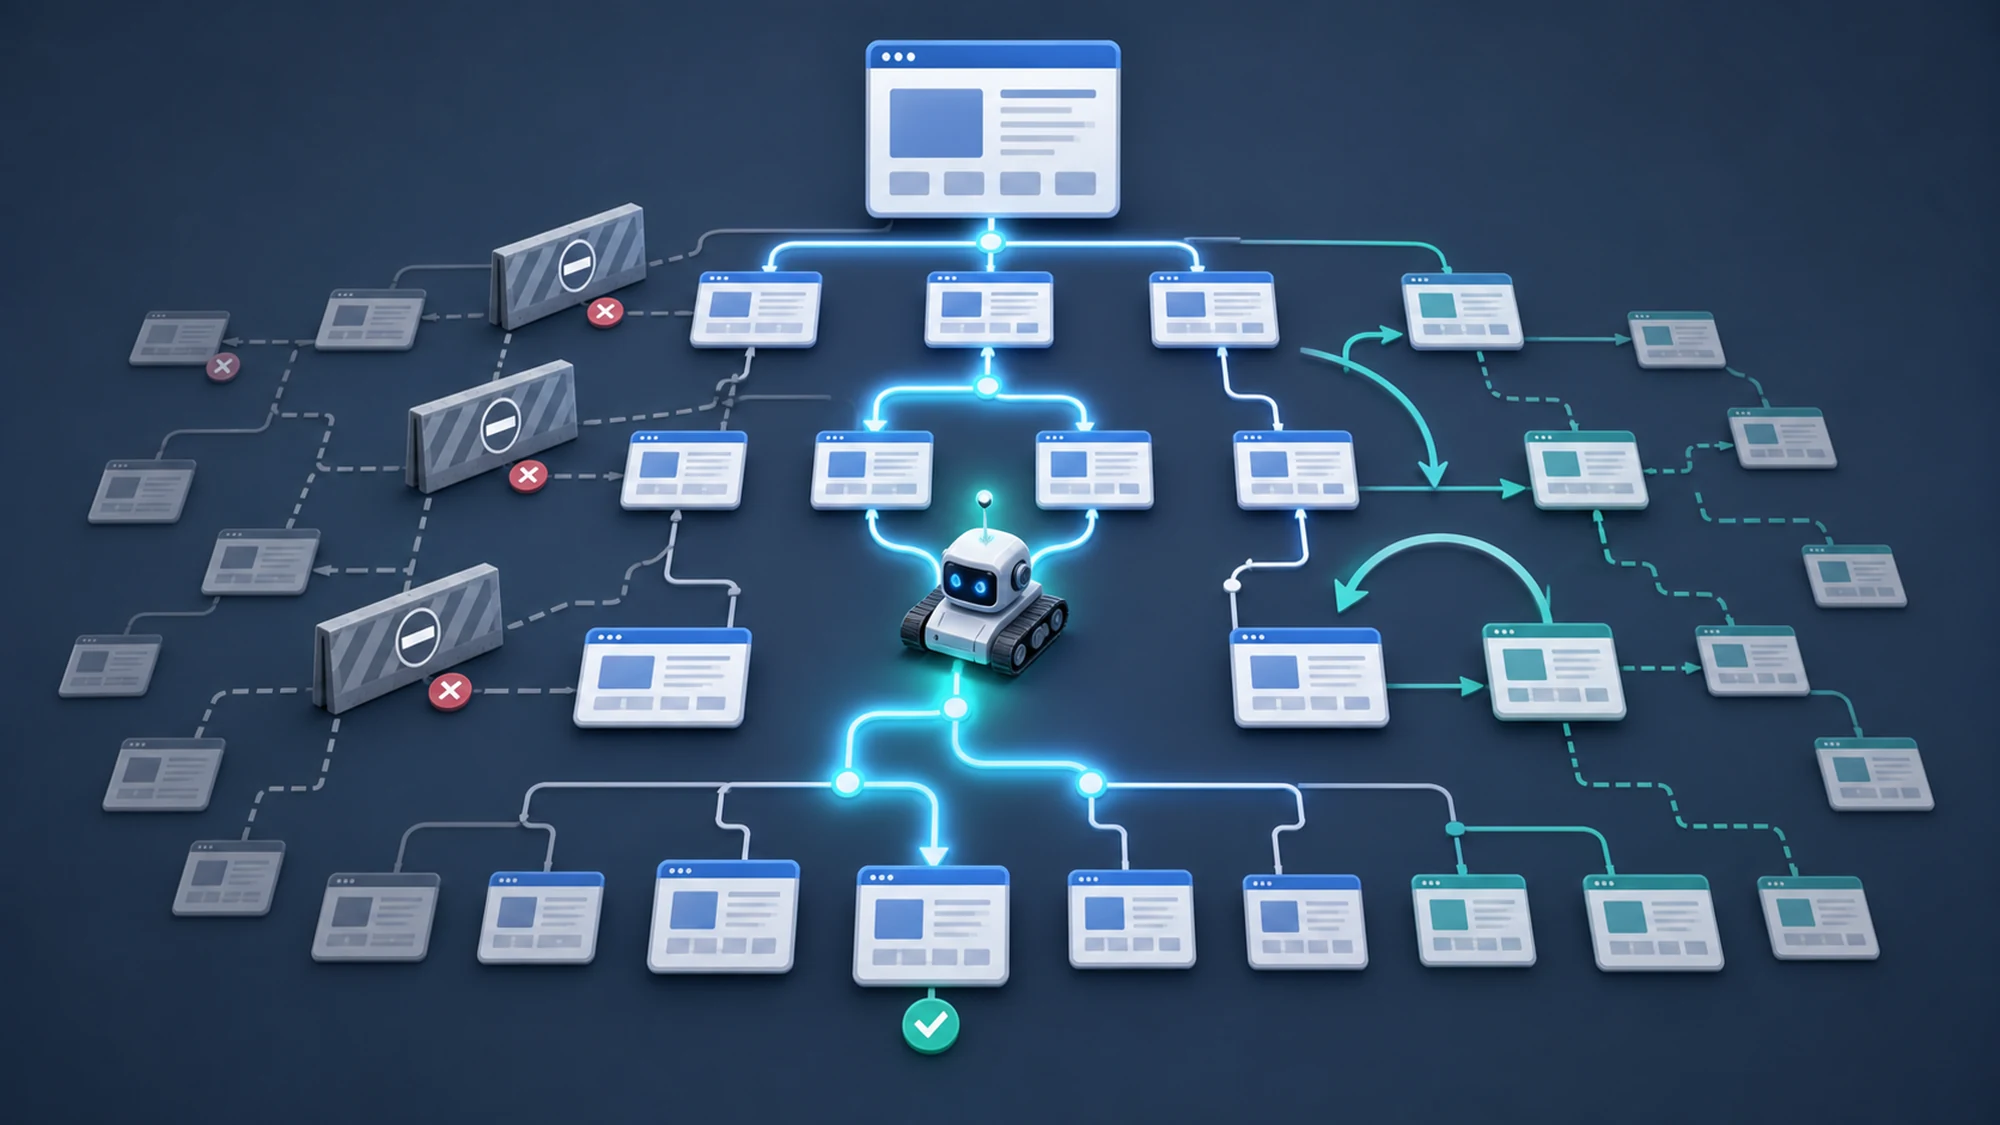
On a site with a few dozen pages, Google has time to visit all of them, regardless of how tidy the structure is. On a site with tens or hundreds of thousands of URLs – online stores with filters and pagination, portals with auto-generated content, multi-language sites – things are different: Googlebot allocates a limited crawl budget for each domain, and that budget can be wasted on low-value pages while important pages stay uncrawled or stale.
Crawl budget is not a setting you flip in a dashboard; it is the combined result of how you use robots.txt, the canonical tag, and indexing directives to guide Googlebot toward the URLs that matter and keep it away from duplicate or low-value variants.
This guide explains what crawl budget actually means, how robots.txt combines with canonical tags and noindex, the most common sources of duplicate content on large sites, and how to check, using real Search Console data, whether Google is crawling your site efficiently.
What Crawl Budget Is and When It Actually Matters
Crawl budget is the number of URLs Googlebot is willing and able to visit on a domain within a given period. Google describes it as a combination of two factors: crawl rate limit (how many requests your server can handle without being overloaded) and crawl demand (how much Google wants to keep your content fresh, based on popularity and how often it changes).
For most small and medium sites, crawl budget is not a practical problem: Google manages to cover all important pages without special intervention. It becomes relevant when the number of unique URLs far exceeds the number of pages that bring real value – a typical situation for eCommerce sites with combinable filters, sites with tracking parameters in URLs, auto-generated archives, or multi-language portals without proper canonicalization.
The clearest sign of a crawl budget problem is when new or updated important pages stay uncrawled for days or weeks, while the crawl stats report in Search Console shows thousands of requests to parameterized or duplicate URL variants.
Controlling Crawling with Robots.txt (and What This File Cannot Do)
The robots.txt file, placed at the domain root, tells crawlers which paths on the site they should not visit. It is a crawling tool, not an indexing tool – a distinction that is frequently misunderstood.
- A
Disallowrule in robots.txt stops Googlebot from downloading that path, saving crawl budget for sections with no value (e.g. internal search results, sorting parameters, admin panels). - Robots.txt does not guarantee that a blocked page will not appear in Google. If the page is blocked but has external links pointing to it, Google can still show the URL in results, without a title or description, because it could not crawl it to see the content.
- Don't use robots.txt to remove pages you explicitly want out of the index; use
noindexfor that, which requires the page to remain crawlable so Google can see the directive.
Practical rule: robots.txt is for saving crawl budget on high-volume, low-value sections (infinite facets, internal search, session parameters), not for fine-grained control over the indexing of individual pages.
Canonical Tags: Preventing Duplicate Content Without Blocking Crawling
The <link rel="canonical"> tag tells Google which is the "official" version of a page when multiple URLs have identical or near-identical content. Unlike robots.txt, canonical does not stop crawling – Google still visits the duplicate variant, but consolidates signals (links, relevance) toward the canonical URL.
Typical cases on large sites where canonical prevents duplicate content:
- Tracking or session parameters (
?utm_source=,?sessionid=): the canonical URL points to the parameter-free version. - Sorting and filtering variants that don't fundamentally change the content (
?sort=price_asc): canonical to the base category page, except for filters that deserve their own indexable page (see the section below). - HTTP/HTTPS or www/non-www versions left active by mistake: canonical (ideally paired with a 301 redirect) toward the final version.
- Syndicated or republished content across multiple subdomains or languages without correct hreflang: a clear canonical pointing to the original source.
A wrongly set canonical – for example pointing to an irrelevant page or the homepage – can do more harm than having none, because Google may ignore the real page in favor of the incorrectly canonicalized target. Always verify that every indexable page has a correct self-referential canonical, not just a value copied from a template.
Robots.txt vs. Noindex vs. Canonical: When to Use Each
The three mechanisms solve different problems and are very often combined incorrectly on large sites. The most common confusion: blocking in robots.txt a page that already has noindex – in this case Google can no longer see the noindex directive, because it isn't allowed to crawl the page, and the result can be the exact opposite of the intent.
| Directive | Stops crawling? | Stops indexing? | When to use it |
|---|---|---|---|
| robots.txt (Disallow) | Yes | Not guaranteed | Saving crawl budget on low-value sections (internal search, session parameters, admin) |
| Meta robots noindex | No | Yes (if the page is crawlable) | Pages that must stay accessible but explicitly excluded from the index (thin filter pages, temporary duplicates) |
| Canonical | No | Consolidates, doesn't block | Duplicate or near-duplicate content, where you want signals kept on one canonical version |
| 301 redirect | No (redirects) | Yes, toward the target | Old URLs, permanently moved, with no need to exist as a separate page anymore |
Quick decision rule: if the page shouldn't exist at all for visitors anymore, use a 301 redirect. If it should exist but is a variant of a main page, use canonical. If it should exist for visitors but not for the index, use noindex, not robots.txt. Robots.txt stays reserved for entire, high-volume sections you don't want crawled at all.
The Most Common Sources of Duplicate Content on Large Sites
Large-scale duplicate content is rarely intentional – it's usually a side effect of technical features added without considering the impact on the number of unique URLs generated.
- Combinable eCommerce filters (size + color + brand) can generate thousands of URL combinations for the same set of products, most with no search volume of their own.
- Pagination without a clear strategy: each page in a long listing (page 2, 3, 4...) can become near-identical content if it has no distinct indexing purpose.
- Session or affiliate parameters kept in the URL instead of a cookie or header, multiplying the same content under different URLs.
- Separate print or mobile versions left over from older architectures, duplicating a page that already exists.
- Auto-generated content from shared sources (manufacturer descriptions, technical sheets identical across multiple sites or categories) with no editorial differentiation.
Not every filter combination should be blocked or canonicalized the same way: a combination with real search volume (e.g. "black leather men's shoes") may deserve its own indexable page, while rare or redundant combinations should be canonicalized to the base category.
How to Check in Search Console Whether Google Is Wasting Your Crawl Budget
This shouldn't be a guess; Search Console provides direct data about what and how much Google crawls on your domain.
- The Crawl Stats report (under property settings) shows the total number of requests, broken down by file type and HTTP response. A high percentage of requests to parameterized URLs or to 404/soft-404 responses is a sign of wasted budget.
- The "Pages" report shows how many URLs are in the "Discovered – currently not indexed" state (Google knows about them but hasn't gotten to or didn't consider it necessary to crawl them) – a large volume here, on important pages, indicates pressure on the crawl budget.
- The "Duplicate, Google chose different canonical than user" category in the same report shows exactly where Google ignored your canonical and picked another version – a clear signal that your canonicalization structure needs fixes.
- Server log file analysis, when available, shows exactly which URLs Googlebot visits and how often, giving a more precise picture than the sample shown in Search Console.
Practical Implementation Plan (Checklist)
- Pull the Crawl Stats report from Search Console and identify sections with high request volume but no indexing value.
- Add explicit robots.txt rules for low-value sections (internal search, session parameters, internal panels), without blocking resources needed for rendering.
- Verify, for every indexable page type, that the canonical tag is a correct self-reference, not a value copied from a broken template.
- Decide explicitly, for each combinable filter type, whether it deserves its own indexable page (real search volume) or a canonical to the base category.
- Replace tracking parameters in URLs with methods that don't generate new URLs, where possible (cookie, server-side processed UTM).
- Use noindex, not robots.txt, for pages that must stay crawlable but excluded from the index.
- Monitor the "Pages" report monthly for growth in "Discovered – currently not indexed" volume or canonical conflicts.
Common Risks and How to Prevent Them
- Blocking in robots.txt a page that also has noindex: Google can no longer see the noindex directive, and the page may stay indexed with minimal information. Mitigation: keep the page crawlable and use only noindex.
- Canonical pointing to a page that redirects or returns 404: a contradictory signal that can make Google ignore the canonical entirely. Mitigation: periodically verify that canonical URLs respond with status 200.
- Blocking JS/CSS resources in robots.txt: prevents Google from rendering the page correctly, even if the base HTML is accessible. Mitigation: explicitly allow access to resources required for rendering.
- XML sitemap including URLs already canonicalized to another page: sends a contradictory signal – the sitemap should only contain canonical URLs. Mitigation: generate the sitemap from the same data source that determines canonicalization, not separately.
- Changing robots.txt without prior testing: an overly broad rule can accidentally block entire sections with real value. Mitigation: test any new rule with the robots.txt testing tool in Search Console before publishing it.
Frequently Asked Questions About Robots.txt, Canonical Tags and Crawl Budget
Does blocking a page in robots.txt guarantee it won't appear in Google?
No. Robots.txt only stops crawling, not direct indexing. If the blocked page has external links pointing to it, Google can still show the URL in results, without a title or description, because it isn't allowed to read the content. For guaranteed exclusion from the index, use noindex on a page that remains crawlable.
How large does a site need to be to require active crawl budget management?
There's no fixed page-count threshold; what matters is the ratio between unique URLs generated and pages with real indexing value. An online store with a few thousand products but combinable filters generating hundreds of thousands of URLs may need active management sooner than an editorial site with tens of thousands of unique articles.
Do canonical tags and 301 redirects do the same thing?
No. A 301 redirect physically sends both the visitor and the crawler to another URL, and the original page is no longer accessible separately. Canonical leaves both pages accessible, but tells the search engine which version to consolidate and display in results. Use 301 when the old page shouldn't exist at all anymore, canonical when multiple variants must remain functional.
Should I block all filter pages in robots.txt?
Not automatically. Some filter combinations have real search volume and deserve to be indexable, with their own content and a self-referential canonical. Blanket blocking of all filter pages can remove from the index pages that would have brought real organic traffic. Analyze search volume before deciding, filter by filter or filter category.
How often should robots.txt and canonical strategy be reviewed on a large site?
As a practical benchmark, review every 3-6 months, plus immediately after any major structural change (site relaunch, new filters added, platform migration). The Crawl Stats report in Search Console quickly shows whether recent changes had the intended effect on crawl budget distribution.
Conclusion
Managing crawl budget on a large site isn't about blocking as much as possible; it's about using robots.txt, canonical, and noindex for the roles they were built for, each separately: robots.txt for entire low-value sections, canonical for consolidating duplicate variants, noindex for pages that must stay accessible but out of the index. Combined incorrectly, these mechanisms cancel each other out; combined correctly, they free up crawl budget exactly for the pages that matter to your business.
Do you have a large site with important pages that are slow to be crawled or indexed? Let's discuss a technical crawl budget audit.
Write a comment